Jev pricing: $0.042 per million input tokens, output free
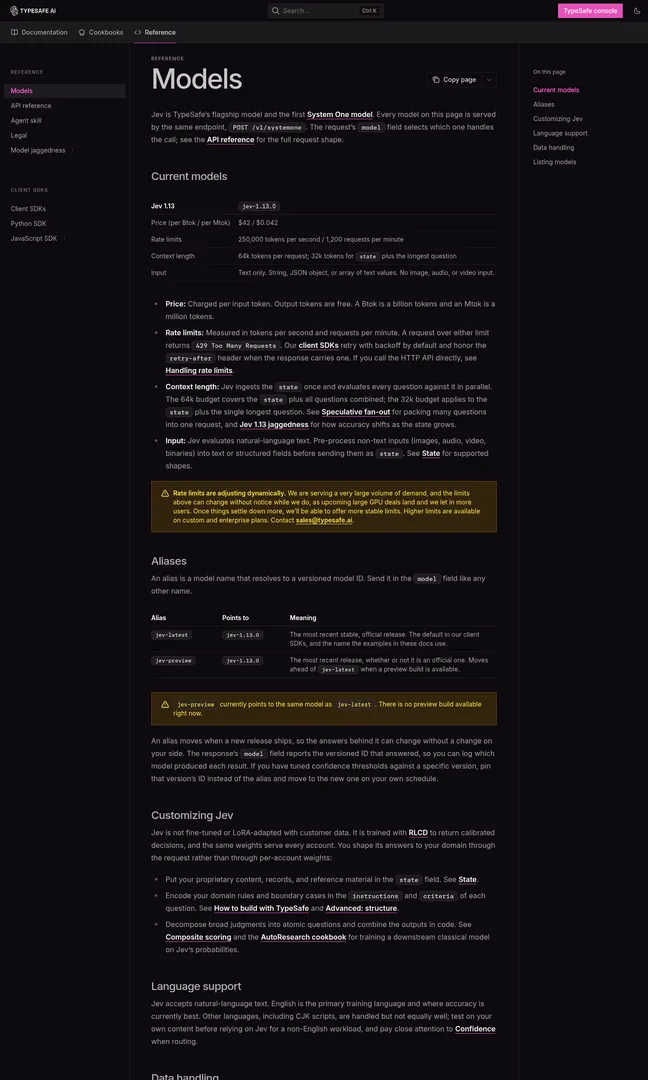
Jev costs $0.042 per million input tokens, and output tokens are free. That is the published price of TypeSafe AI's first model, in early access since 15 September 2026, and it is the only figure in the launch a buyer can check without trusting the vendor. Everything below is either arithmetic on that price or a claim with a label on it.
What you are buying, in the vendor's words: a "System One" model that returns typed, schema-constrained values with a probability distribution, instead of text. It does not generate strings, so it cannot return a paragraph where you asked for a category. What Jev actually returns is covered separately on this site.
The arithmetic
Take an RFQ triage job: one document in, one of a dozen categories out, with a confidence figure. Call it 2,000 input tokens per document. At $0.042 per million that is $0.000084 a document, or $8.40 for a hundred thousand documents a month. TypeSafe's own comparison table puts current LLM input prices at $0.20 to $10 per million, with output tokens about five times dearer than input. The same hundred thousand documents on the cheapest of those rates cost $40 before any output tokens; on the dearest, $2,000 before output.
That is the whole commercial case. Not intelligence, not speed. A classify-route-score call that costs cents instead of dollars, and a bill that does not depend on how many tokens the model chooses to say back.
Before you use that figure, check the two limits that change it. Jev takes 64k tokens per request, with 32k of that the budget for your state plus the longest question, so a long document has to be cut down before it is priced. And you can put several questions in one request against the same state, which means a document you were going to classify, score and check for duplicates is one call and one input charge, not three.
The claims, labelled
| Claim | Vendor's figure | Status |
|---|---|---|
| Input price | $0.042 per million tokens | Published; vendor says it "can't prove it isn't subsidized" |
| Output price | Free, "too cheap to meter" | Published |
| Latency | 70–500 ms end to end, against 3–329 s for frontier models | Vendor-measured, "from our laptops on the West Coast" |
| Workflow evals | 193.6x faster, 444.6x cheaper | Vendor's own workflows, written by its own team; vendor calls these "the higher end of real world gains" |
| Type errors | 0% | By construction, "not empirical"; the schema is fixed before the call |
| Public benchmarks | None | Not published, by the vendor's own choice |
| Enterprise terms, SLA, data residency | None | Not published; early access by waitlist |
The latency line drew the sharpest reply on Hacker News, and it is a fair one:
"70-500ms vs 3-329 seconds" are apples-to-oranges unless the LLM baseline is doing comparable work. If Jev is skipping generation entirely for a narrow structured task, of course it's faster.
— ramon156, on Hacker News
Correct, and it does not change the bill. Nobody is proposing Jev for work that needs a paragraph back. The comparison that matters is the same narrow task on both models, with the LLM forced into structured output, which is what TypeSafe says its workflow evals do. Those evals are the vendor's. Run your own.
What to do with the number
Pull last month's model invoice and tag every call that is a classify, route, score, extract or validate. That is the addressable spend, and it is the figure to carry into any conversation with TypeSafe or with a client paying you per document. Then build the acceptance test before the key arrives: a few hundred documents your team has already labelled, run through the schema. The check is calibration, not accuracy alone — if the model puts 90 per cent probability on an answer, it should be right about nine times in ten on that slice, and if it is not, the probability is decoration and the pricing case goes with it.
Sign nothing annual yet. There are no enterprise terms, no SLA and no deprecation policy published, published rate limits can change without notice, and a client in a regulated market will ask where the data goes before it asks what it costs. Until those lines exist, the price makes Jev a cost line in your own tooling rather than something to put in a client's architecture diagram.
A view, labelled as one: budget on $0.042 holding through the first quarter of 2027. TypeSafe says it expects the price to fall rather than rise, and a launch price that moves up is a launch that failed.
To have your own invoice sorted into decisions and sentences, and the cheap half moved, Vesprr does that work — or tell us what you are classifying.
Sources
- Introducing System One Models & Jev, Diogo Almeida, TypeSafe AI, 15 September 2026 (price, latency, eval and hallucination claims, and every quoted caveat)
- Models, TypeSafe AI docs, read 24 September 2026 (published price, 64k request limit, 32k state budget, rate limits)
- Hacker News discussion, 15–16 September 2026 (comment by ramon156)
- Also on this site: What is Jev? TypeSafe AI's model that returns types, not text (24 September) and AI agent acceptance test: the free chess honeypot (14 September)